The backup that proves it ran.
Nobody notices a broken backup until restore day. Give the job a heartbeat: if the ping does not arrive on time, the silence becomes an incident and notifies your matching alert channels.
1 · Create the heartbeat
In the app (Scheduled jobs → New) or via API:
curl -s -X POST https://app.upfour.io/v1/heartbeats \
  -H "Authorization: Bearer $UP4_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{
    "name": "nightly pg_dump",
    "expected_interval_seconds": 86400,
    "grace_period_seconds": 3600
  }'
The response carries the slug — that slug is the ping URL.
The deadline starts with the first check-in: a job that never pinged never alerts, so run the
script once by hand after step 3.
2 · Size the grace window
The job runs daily (86400), but not to the second: the
dump takes 20–40 minutes depending on load. The grace window absorbs that spread —
interval = the schedule, grace = the jitter. One hour of grace on a daily backup means:
alert only when the ping is more than an hour late. Too tight pages you for a slow night; too
loose costs you reaction time.
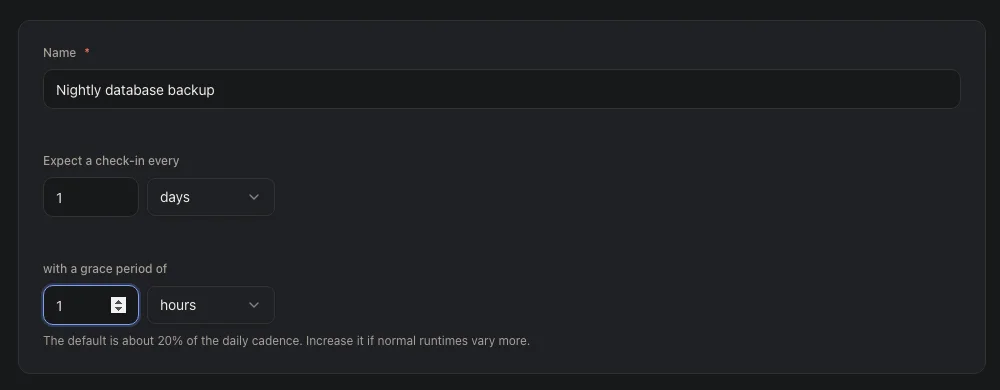
Visual guide · Scheduled jobs / Create
- Job nameGive the job a name you will recognize in an alert.
- Expected intervalThe example job runs once per day. Set this to the job’s actual schedule.
- Grace periodOne extra hour allows for a late finish. Send the ping only after the job succeeds.
3 · Save the backup script, then schedule it
Save this as /usr/local/bin/up4-nightly-backup.sh, replace the database,
backup path and ping URL, and make the script executable. Run it with Bash:
#!/usr/bin/env bash
set -euo pipefail
pg_dump mydb | gzip > /backups/nightly.sql.gz
curl -fsS --max-time 10 --retry 3 \
  https://app.upfour.io/v1/heartbeat/<your-slug>
Then add this single line to the backup user’s crontab, after checking that user can run the script and write the backup file:
30 3 * * * /usr/local/bin/up4-nightly-backup.shThree details carry the whole recipe:
set -euo pipefail | Bash stops on failure, including a failed dump inside the compression pipeline. Without pipefail, gzip can succeed after pg_dump fails and the script would send a false success ping. |
-f | curl exits non-zero on HTTP errors instead of swallowing them. |
--max-time 10 --retry 3 | A hanging ping must not block cron; a transient network blip should not look like a missed backup. |
4 · What happens when it breaks
Backup fails → no ping → interval + grace passes → incident opens and the
alert channels that match the job are
notified (jobs have no alert plan, on-call rotation or phone call);
heartbeat.missed goes out as a webhook. The next
successful ping recovers it and sends the all-clear. The ping log keeps accepted, stored
check-ins with timestamp and source IP — GET /heartbeats/{id}/pings
answers “did it really run on the 14th?” for 90 days (the IP is cleared after 7).
Variants
Weekly jobs: 604800 with a day of grace. Multiple backup
hosts: one heartbeat each — a shared heartbeat can't tell you which host went quiet.
Migration downtime: pause the heartbeat, resume after; paused heartbeats never alert.
Was this page helpful?